


Nvidia has spent the past few years touting what it calls "AI factories" – mammoth cathedrals to compute that are essentially just AI-centric data centers. While many in the industry look straight for shiny graphic processing units (GPUs), for folks in the networking space a debate has raged for quite some time over exactly how to connect these sites.
But according to Nvidia's SVP of Networking Gilad Shainer, most of that debate has been focused on the wrong problem and the hardware many vendors are selling to solve it may be making things worse.
The scale-up (connections within a server) and scale-out (connections between servers/racks) spaces are increasingly well-defined through the myriad initiatives like the Ethernet for Scale-Up Networking (ESUN), the Ultra Ethernet Consortium (UEC), and most recently the Optical Compute Interconnect’s Multi-Source Agreement (OCI-MSA) group.
But in a conversation during Nvidia’s GTC event earlier this year, Shainer took issue with approaches toward the nascent layer of data center interconnectivity: scale-across.
On paper, the idea is sound: connecting multiple distributed data centers into a kind of AI super factory via a long-haul fabric that helps to pool resources across hundreds to thousands of miles. Already, vast projects like Amazon’s Rainer or Microsoft Fairwater have set the bar high as to what scale-across could achieve as it begins to take shape.
The Nvidia networking chief, however, argued that deep-buffer, off-the-shelf switches for scale-across being touted by rival vendors are fundamentally wrong for AI workloads.
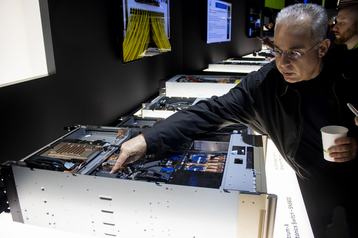
Deep-buffer switches, Shainer explained, were designed for long-distance traffic where unpredictable latency is a given, the logic being that if data might take a long time to reach its destination you'd rather hold it in a large buffer than risk dropping it and starting the journey over. Cisco with its P200-powered lines and Broadcom’s BCM88370 are among vendors offering such switches, and Shainer noted that the approach is perfectly reasonable for traditional networking.
For AI, though, the SVP claimed the concept creates a different problem, with the act of draining a full buffer back out through the same pipe it came in on introducing three-times the latency of the original distance.
“I’m dealing with something larger, I don’t want to deal with three-times the time. It’s stupid. I could actually connect continents from that perspective, and I’m just wanting city to city, and I need to pay for a continent transfer, that doesn't make sense,” Shainer said.
The consequences of the deep buffer approach are already known to those in the networking space, with Shainer saying previous attempts to deploy deep-buffer switches for scale-out inside data centers have already been tried and failed.
“It was like a disaster after disaster after disaster,” Shainer said. “The buffer is your enemy. The buffer is a generation of jitter.”
Nvidia’s answer to deep buffer uncertainty culminated in Spectrum-XGS, with adaptive distance congestion control, precision latency management, and end-to-end telemetry marketed as more attuned to AI’s latency sensitivity than deep buffer rivals.
And though the concept of scale-across typically looks to data centers distributed across vast distances, Shainer detailed that the underlying algorithm kicks in at distances greater than 500 meters (1,600 feet). At that range, the technology lauded for potentially interconnecting facilities across great distances could then well be used for building to building within a campus.
“We have a good amount of customers, for example, that [are] already doing those distances when you look at large AI factories,” Shainer said. “So this is what they are already using Spectrum-XGS for.”
Spectrum-X: Growing in all dimensions

Nvidia thinks it has dethroned Cisco as the world's biggest networking company
Nvidia's reinvention of Ethernet for AI workloads has quickly and quietly made it a networking powerhouse
Spectrum-XGS may be the new arrival in Nvidia’s networking portfolio, but its Ethernet fabric has already redrawn the competitive landscape.
Since the Ethernet-based fabric’s launch in 2024, demand for Nvidia’s Spectrum-X is now “roughly on par with InfiniBand,” putting it directly in competition with switch lines from both Cisco and Arista Networks, according to IDC.
Shainer was coy on specifics, but said he’s seen growth coming in “all dimensions.”
In his view, the origins of that growth stem from a deliberate design choice made when Spectrum-X was conceived. Where InfiniBand was long the gold standard for distributed AI computing – and to many in the world of high-performance computing (HPC), it still is – the problem was that AI simply wasn’t sticking.
As accelerated computing began spreading into enterprises and hyperscalers more accustomed to Ethernet, Shainer explained that asking teams to abandon familiar management tooling for InfiniBand's steeper learning curve simply wasn't realistic, adding: “There is no time on AI.”
The solution was to port as much of InfiniBand's DNA into an Ethernet framework as the architecture would allow. Lossless transport and adaptive routing came over, along with congestion control.
What couldn’t make the journey across were InfiniBand's reduction algorithms, which is why Shainer noted that some customers running inferencing workloads still reach for InfiniBand and why the two fabrics increasingly coexist rather than compete within the same environment.
The breadth of operating systems Spectrum-X has accumulated is perhaps the clearest sign of its traction, with Cumulus, Sonic, FBOSS, and even Cisco's own NX-OS, which runs on Cisco switches built around Spectrum-X ASICs.
“I don't think there are many examples out there of a networking company buying equipment from another networking company to do that,” Shainer said.




Comments