

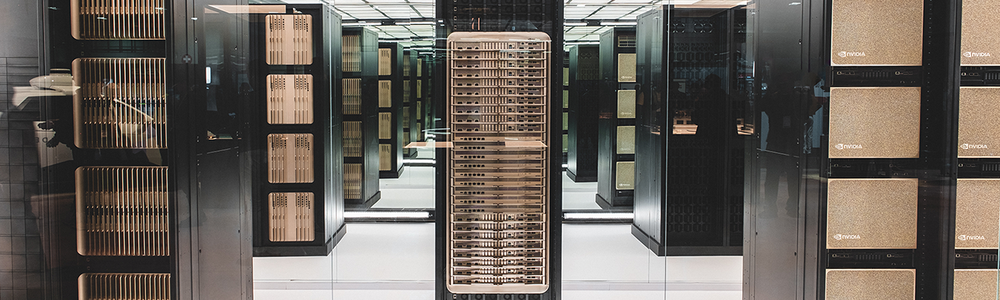
The big four cloud giants are turning to Nvidia's Dynamo to boost inference performance, with the chip designer's new Kubernetes-based API helping to further ease complex orchestration.
According to a blog post, Amazon Web Services (AWS), Google Cloud, Microsoft Azure, and Oracle Cloud Infrastructure (OCI) are all making use of Nvidia Dynamo, a software platform designed to drive more efficiency for inference workloads across disparate GPUs.
Nvidia has now integrated Dynamo into managed Kubernetes services, tapping containerized application management in a bid to boost performance when running multi-node inference loads.
Nvidia revealed that AWS, for example, is using Dynamo to accelerate inference for customers running generative AI workloads. It’s also been integrated with Amazon’s Elastic Kubernetes Service (EKS) to scale disaggregated serving for Kubernetes both on AWS and on-premises.
Google Cloud, meanwhile, is employing Dynamo to optimize large language model (LLM) inference on its cloud-based supercomputer platform, AI Hypercomputer.
Azure is tapping the offering to power multi-node LLM inference on its GB200-v6. Microsoft's Blackwell-based virtual machines were already performance leaders in inference, having helped the MLPerf Inference record, offering 865,000 tokens per second – only to be usurped by the hyperscaler’s next-gen VM, the GB300 v6.
The team at OCI is utilizing Nvidia’s Dynamo to support multi-node LLM inferencing on its Superclusters. These mammoth computing clusters already feature custom-designed networking that uses RDMA over Converged Ethernet Version 2 (RoCE v2) on top of Nvidia ConnectX-7 network interface cards (NICs) – enabling it to provide 400 Gb/s connections between GPUs.
Augmenting Dynamo is Grove, a recently introduced open source Kubernetes API that Nvidia engineers built to help developers run workloads more efficiently across thousands of GPUs.

Nvidia unveils Grove: An open source API to help orchestrate AI inference
Offering turns complex orchestration needs into simple Kubernetes pods
Available as a modular component within Dynamo or separately via GitHub, Grove offers autoscaling components that turn complex orchestration needs into what are essentially simple Kubernetes pods.
Many of the hyperscalers employing Dynamo are building out distributed data centers to power AI workloads. These facilities are either like AWS’s Rainier site, in which multiple facilities on a single campus are interconnected to run AI workloads, or, in the case of Microsoft and its growing Fairwater project, separated by hundreds of miles.
Software platforms like Dynamo, paired with tools like Grove, are being brought in to not only keep packets moving across disparate sites but also ensure they’re being transmitted effectively and efficiently at incredible speeds.
It’s not just the big four hyperscalers that are employing the Nvidia platform to scale multi-node inference, either. Nebius, the European neocloud touting multi-billion dollar deals with Meta and Microsoft, is also making use of Nvidia’s Dynamo platform, becoming an ecosystem partner back in May to support customer AI workloads.
“As AI inference becomes increasingly distributed, the combination of Kubernetes and Nvidia Dynamo with Grove simplifies how developers build and scale intelligent applications,” Shruti Koparkar, senior manager of product marketing, AI inference at Nvidia, wrote in a blog post.


Comments