

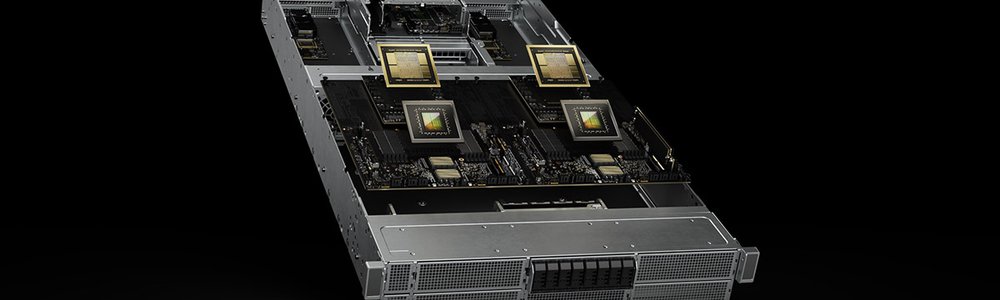
Nvidia’s rack-scale Blackwell systems topped a new benchmark of AI inference performance, with the tech giant's networking technologies helping to play a key role in the results.
The InferenceMAX v1 benchmark, released this week by SemiAnalysis, evaluates inference efficiency across GPUs from top-tier hardware vendors, testing throughput, latency, and total cost of ownership (TCO) when running frameworks like vLLM, SGLang, and TensorRT-LLM. The benchmark is open source and runs nightly to reflect software and firmware improvements in near real time.
SemiAnalysis found Nvidia’s GB200 NVL72 rack-scale system to have the strongest performance across metrics, including throughput-per-dollar and tokens-per-megawatt, outpacing rival systems like the AMD MI355X.

Following the tests, an Nvidia technical blog attributed much of the performance to its networking technologies, including its NVLink, NVLink Switch, and the NVL72’s rack-scale networking fabric, which the chip giant claimed helped to reduce communication overhead on large-scale inferencing.
Nvidia engineers wrote that the GB200’s fifth-generation Tensor Cores and the NVLink Switch’s 1,800 GB/s bidirectional bandwidth help to eliminate traditional PCIe bottlenecks while remaining fully utilized.
In addition to networking breakthroughs, Nvidia’s performance was attributed to software innovations. The addition of routinely updated inference frameworks like TensorRT-LLM and Dynamo helped to bring down cost levels for running intensive AI models when compared to rival systems.
“Inference demand is growing exponentially, driven by long-context reasoning,” said Nvidia founder and CEO Jensen Huang. “Grace Blackwell NVL72 was invented for this new era of thinking AI. Nvidia is meeting that demand through constant hardware and software innovation to enable what’s next in AI.”
The benchmark-topping GB200s are already available at scale from providers like CoreWeave, with the likes of IBM, Mistral AI, and Cohere among the early customers to have gotten their hands on the servers.
But just as the GB200 NVL72 came out on top, Nvidia announced that Microsoft launched the world's first at-scale production cluster of the next generation of the rack server: The GB300 NVL72.
The next-generation offering is being deployed for ChatGPT maker OpenAI, featuring more than 4,600 Blackwell Ultra GPUs that are connected using Nvidia's InfiniBand-based Quantum-X800 networking platform.
More tests to come
While the results are in from the initial SemiAnalysis benchmark, the analyst firm plans to continuously re-benchmark inference workloads across vendors to reflect daily software and hardware updates.
It also plans to subject other hardware to its tests, including custom offerings like Google’s TPUs and Amazon Web Services’ Trainium systems.
Both AMD and Nvidia collaborated on the open benchmark, with SemiAnalysis noting that results vary by workload and precision format.
“Open collaboration is driving the next era of AI innovation,” said Dr. Lisa Su, AMD’s chair and CEO. “The open-source InferenceMAX benchmark gives the community transparent, nightly results that inspire trust and accelerate progress.”




Comments