


LONDON – Network operators are discovering that AI for network operations is less about revolutionary technology and more about solving fundamental data engineering problems.
Vishnu Acharya, Uber’s head of network infrastructure for EMEA, during this week's DCD Compute event outlined a familiar evolution from earlier days of network monitoring: “The initial challenge for us was actually lack of visibility,” Acharya said, referring to Uber's early data center buildout starting in 2014, adding: “We actually had incidents and things go on in the network where we didn't catch it.”
Flash forward more than a decade, and Acharya told the DCD Compute audience that the pendulum has now swung too far in the opposite direction. “Now we've almost overcompensated,” he explained. “What we're really grappling with is almost too much data when it comes to telemetry about our network.”
This data overload manifests in cascading alerts from single failures. When a physical link fails in a highly redundant network, operators receive alerts from both ends of the connection, plus higher-level protocol failures as the event propagates up the stack – making it overwhelming at times to make sense of the information overload.
“Computers can do that much, much faster than humans at correlating these events," Acharya noted, adding that organizations still struggle with the tendency to monitor “every single aspect” of their networks.
According to Acharya, Uber's approach to solving the data overload problem involved a fundamental shift in monitoring philosophy. Rather than collecting metrics from every network component, his team focused on connecting network performance to business services.
“Making that connection between network performance and services was key,” he said. “Once we did that, we realized you don't need to monitor everything on your network.”
By adopting a service-level indicator (SLI) approach, Uber found it proved more effective than traditional component monitoring, adding: “We moved from a component model to more of an SLI model, thinking about what are the SLIs that are important to us and to the business and to the services.”
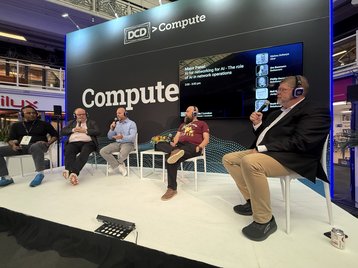
Neil McRae, chief network strategist at Juniper Networks and a former network architect at several major carriers, emphasized that having data isn't the same as having useful data.
“Everyone says [carriers] have got loads of data, and it's true, but it's what's actually valuable,” McRae said. “We're plotting the temperature of this device. Meanwhile, you're running out of power. It's trying to understand, almost building a model hierarchy of all the data that we need, and actually ensuring that if that hierarchy is missing something, we need to figure out what that is.”
That challenge extends beyond just collecting the right metrics, with McRae reminiscing from his time in telecom: “I've worked with every telco on the planet. None of them have got clean data,” McRae stated bluntly. “They've spent billions trying to clean it up.”
Urs Baumann, a network automation engineer at Swisscom, reinforced this point: “In the past, we had this 'big data' trend, and everyone was thinking, we have to collect all the data. But the thing we find out now is that the quality of data – just collecting data is not enough. We need to have data in the right quality, to clean up data, to bring data to the right quality, [and] to label the data. This is an immense amount of work.”
The 75% rule
Phillip Gervasi, co-founder of Solutional, provided a sobering reality check about AI project allocation, suggesting 75 to 85% of any AI project is going to be the data pipeline and engineering parts – not even the data analysis.
Gervasi said this creates organizational challenges because network operations teams “don't have data engineers and data analysts.”
The result is that many proof-of-concept projects never progress to production. “There's no clear understanding of when this POC is successful,” Gervasi explained, noting that conversations often end with enterprises saying they need to “get our data situation in order first, and that's going to take us a lot of time.”
The autonomy reality check: Setting realistic expectations
The panel revealed that successful AI implementations in networking focus on specific, bounded problems rather than attempting full network autonomy.
Among the approaches that proved more successful were retrieval-augmented generation (RAG). Here, Gervasi outlined, organizations can point large language models (LLMs) at internal databases of network flows and telemetry, allowing engineers to query network status in natural language.
Another of the more practical approaches to autonomy outlined by the panel was for root cause analysis. Instead of pursuing full automation, they argued that there’s greater success in using AI to assist in trouble shooting to quickly identify probable causes of network issues.
When asked about progress toward autonomous networks, the panelists provided mixed assessments.
Baumann was skeptical: “We still have the same issues we had 20 years ago with SDK quality, with bugs, with all these things. The hope is, with AI, we can solve all these issues we could not solve before. But I don't think the quality of this kind of stuff gets better just because we have AI.”
McRae took a more nuanced view, pointing out that networks already operate autonomously in many areas. “BGP is doing its thing right now. In the last five minutes, we've probably had 50,000 route updates. No one knows about it, but the network has just done it.”
The consensus emerged that rather than pursuing full autonomy, the industry should focus on automating specific, well-defined network operations where AI can provide clear value.
“I don't think we ever get to fully autonomous,” McRae said. “I don't think we need to get to fully autonomous.”
Acharya raised an important question about expectations for AI systems versus human operators. “Many times I'm working through intuition,” he said about network troubleshooting. “Am I being unreasonable for expecting a model to be 99% accurate when I'm probably 92%?”
This tolerance for imperfection may be key to successful AI deployment. As McRae noted, “If we get to 90%, that might be okay for a lot of use cases.” However, he also highlighted the double standard that AI systems face: “If we're depending on AI system to do operations and it causes an outage that costs millions of dollars, we're going to be much harder on that than when humans make mistakes.”


Comments