

AI inference platform FriendliAI sits in a unique place in the AI system. Founded in 2021 by CEO Byung-Gon Chun at South Korea’s prestigious Seoul National University, the company moved its headquarters a few years later to the U.S., specifically Redwood City, California. Among its ecosystem, therefore, one will find American giants like Nvidia, while some of South Korea’s leading telecom players count as customers.
FriendliAI also offers a unique take on the current memory crisis hitting the industry, especially as inference becomes the dominant AI use case. As recently explored by SDxCentral, 2026 is tipped to be the breakout year of AI inferencing, the process where a trained machine learning (ML) model creates outputs and predictions from new input data.
The inference demand has seen various announcements from hyperscalers, open clouds, neoclouds, and networking stalwarts such as Cisco. On the telecom side, the likes of Verizon, AT&T, and Deutsche Telekom have dipped their toes into inference with Nvidia-based ventures.
One major snag is memory, or rather the lack of it due to worsening supply chain issues. As Chun told SDxCentral in an exclusive interview, customers big and small are having size issues with AI models, which can span between five billion to one trillion parameters in scope.
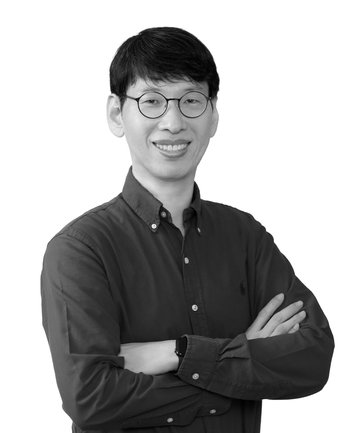
The CEO explained larger enterprises handling a lot of traffic need to reduce the number of GPUs which they run. For small companies, meanwhile, it’s a case of elasticity.
“It's more like whether they can use it they want to use it instead of running their model all the time," Chun said. "We really focus on how to run those models very efficiently, and that's related to speed, latency, and throughput, meaning how many GPUs you need to serve many, many clients coming in. And that's really critical, and that's also connected with scalability and reliability.”
In FriendliAI’s eyes, the solution is quantization, which enables models to use lower-precision formats like 8-bit floating point (FP8), 8-bit integer (INT8), and adaptive weight quantization. Such formats can reduce memory use and computational demands while maintaining prediction accuracy.
Quantization is already widely used across the AI stack. Where FriendliAI has been turning heads to the tune of $20 million with its core offering Friendli Inference, specifically in how it schedules and executes multiple concurrent model requests on GPUs.
“We have our own runtime that's optimized using a more optimized version of continuous batching, fine grained, token level caching, and our own kernel library, which are highly optimized for dynamic tensor shapes,” Chun explained. “A lot of times you have many different dynamic things going on because you have more requests or smaller requests, you have longer inputs or smaller inputs, and get longer outputs and smaller outputs, and all these things are really dynamic tensor shapes.
“Tensor is not static,” the exec added. "It has varying shapes over time, and we always think about how to process all those dynamic tensor shapes very efficiently.”
FriendliAI’s chief also touted user experience as being pivotal to the platform, claiming quantization is a one-click journey through Friendli Inference.
“When the model is loaded, it is automatically quantized and then just run. That's very important for saving memory and then using a small number of GPUs," Chun said.

Will memory fail the AI boom?
How the memory crunch is reshaping the AI infrastructure market and pushing costs downstream
The value of video
Customers currently using FriendliAI to transition AI prototypes into production include South Korean telecom giants SK Telecom (SKT) and KT. But the firm is not South Korea centric, with Chun noting that starting on a South Korean footing meant it entered the U.S. market later than he preferred.
The CEO highlighted U.S. customers like San Francisco’s Twelve Labs, a video intelligence firm that uses AI to process video data, confirming similar booming use cases for inference from Cisco and Akamai as powered by computer vision.
On the agentic side, Chun noted FriendliAI is powering personal agents for SKT.
“We are not supporting the entire workflow there, but we are really providing inference of specific parts of their workflow,” Chun explained, adding the firm was currently in talks with operators in South Asia.
While the firm has Asian roots, FriendliAI expects its U.S. base to be double the projected size of its South Korean operations, numbering 60-strong in the U.S. by year end, up from its current total of 45.
"Since our $20 million funding round last summer, we've been scaling our go-to-market (GTM) in the US market. So we started to build GTM strongly, and the team is expanding quite quickly," Chun said. "With the GTM, we are hoping to help more companies in the U.S., starting from large scale, AI-native startups and also enterprise companies that use AI models, in particular, open source models."
Chun stressed South Korea is “really advanced” in terms of AI inference usage compared to other markets within Asia-Pacific, singling out South Korean government efforts in funding sovereign foundation models. These efforts currently center around five consortia: SK Telecom, Upstage, Naver Cloud, NC AI, and LG AI Research.
“That's really driving a lot of attention and a lot of technology advancement within Korea and we are basically providing inference for these models at the moment," Chun said.
On the hardware side, FriendliAI is closely aligned with Nvidia and optimized for its Blackwell GPUs, while also supporting AMD chips. Chun expects to keep a good relationship with Nvidia even as it continues on an AI-driven spending spree with the likes of AI chipmakers Groq, Slurm-makers SchedMD, and possibly software firm AI21.
“We are really closely working together with Nvidia to launch future models, as well. And we are expanding our product to cover much more complicated inference pipelines," Chun said. "So that's our focus in 2026.”

Comments